Machine Learning
Predictions that pay for themselves.
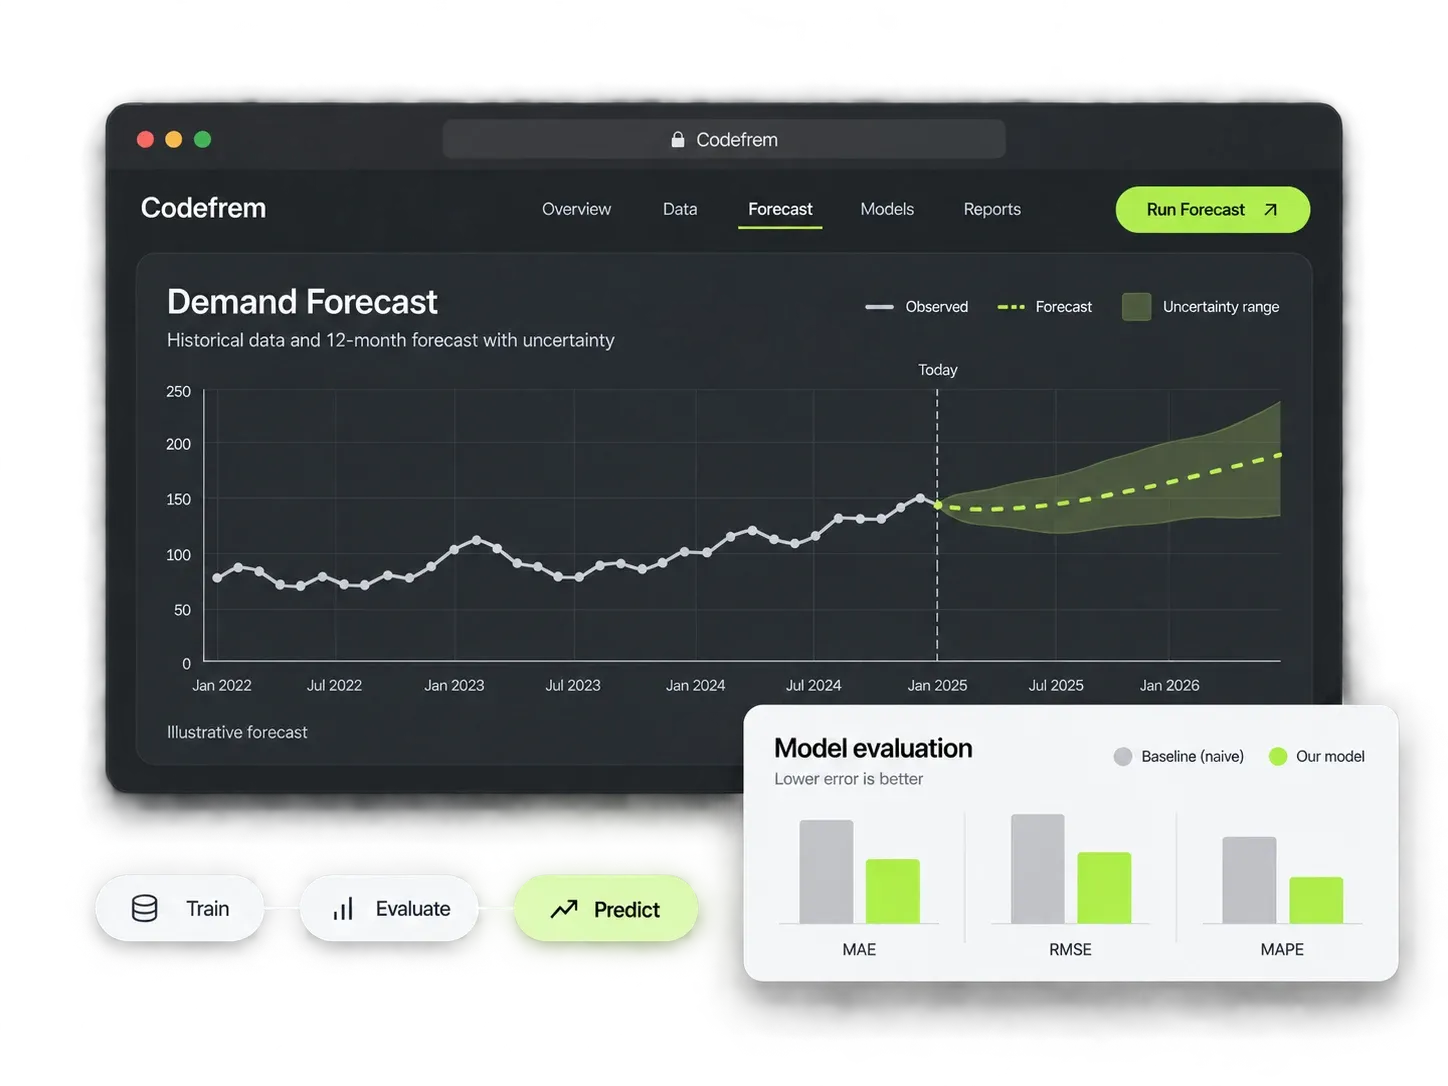
We build machine learning models that solve real business problems: forecasting demand, scoring leads, spotting anomalies. No research papers, no hype: working systems measured by the money or time they save.
Machine learning is appropriate when a repeatable prediction or classification can improve a real workflow and suitable data is available. We first assess feasibility, label quality, data permissions, and a simpler baseline. Success criteria are agreed around business usefulness as well as model performance, before investing in a more complex approach.
Development includes preparation, training, and evaluation on held-out data, with checks for leakage and relevant error patterns. You receive a documented model or service, evaluation findings, limitations, and an integration plan. Production monitoring and retraining can be added to the scope. Accuracy is measured on the available data; we do not promise an arbitrary score or assume that a model is always the best solution.
Built around your problems
Every line item below exists because a client once paid the price of not having it.
Starts with the problem
We tell you honestly when ML is overkill and a spreadsheet rule works better. If we build, it's because the math pays off.
Your data, working harder
The history you already have (sales, tickets, logs) becomes forecasts, scores and early warnings.
Measured honestly
Accuracy and business impact baselined before we build, reported after. You'll know if it's working.
Integrated, not a demo
Predictions land inside the tools your team already uses: dashboards, your app, email alerts.
Explained in plain English
We document what drives each prediction. No black boxes your team can't reason about.
Handover without mystery
Code, docs and a retraining pipeline included. The system keeps working long after we're gone.
Our stack
Pick a plan
Clear scopes, fixed prices. Every plan can be tailored: the quote you approve is the invoice you pay.
$1,500
Feasibility first: know before you build.
- Signal study on your data
- Working prototype
- Go / no-go report
- Baseline comparison
$2,600
A production model in your workflow.
- Full model build + validation
- Integrated into your tool
- Drift monitoring
- Retraining script + docs
$4,500
Measured impact, not just accuracy.
- Multiple models / ensembles
- Production API + auto-retraining
- A/B measurement of impact
- 3 months of priority support
$1500
4-6 weeks
Final quote depends on scope: you always get a fixed price before we start, so there are no surprises.
Questions clients ask
How much data do we need?
Depends on the problem, but usually months of history are enough to start. The feasibility study answers this precisely for your case before you commit to the full build.
What if it doesn't work?
That's what the feasibility phase is for; we check signal quality before the big spend. If there's no signal, we tell you early and you've spent a fraction of the budget learning it.
Where do the models run?
Wherever suits your setup: a small cloud VM, a serverless function, or inside your existing infrastructure. We size it for cost, not for a demo.
Do we need to hire an ML engineer afterwards?
No. Handover includes docs, retraining automation and a training session. Most clients run the system themselves and call us only when their business changes.
LET’S WORK TOGETHER
Ready to get started?
Tell us about your machine learning project; we reply within a day.