Data Engineering
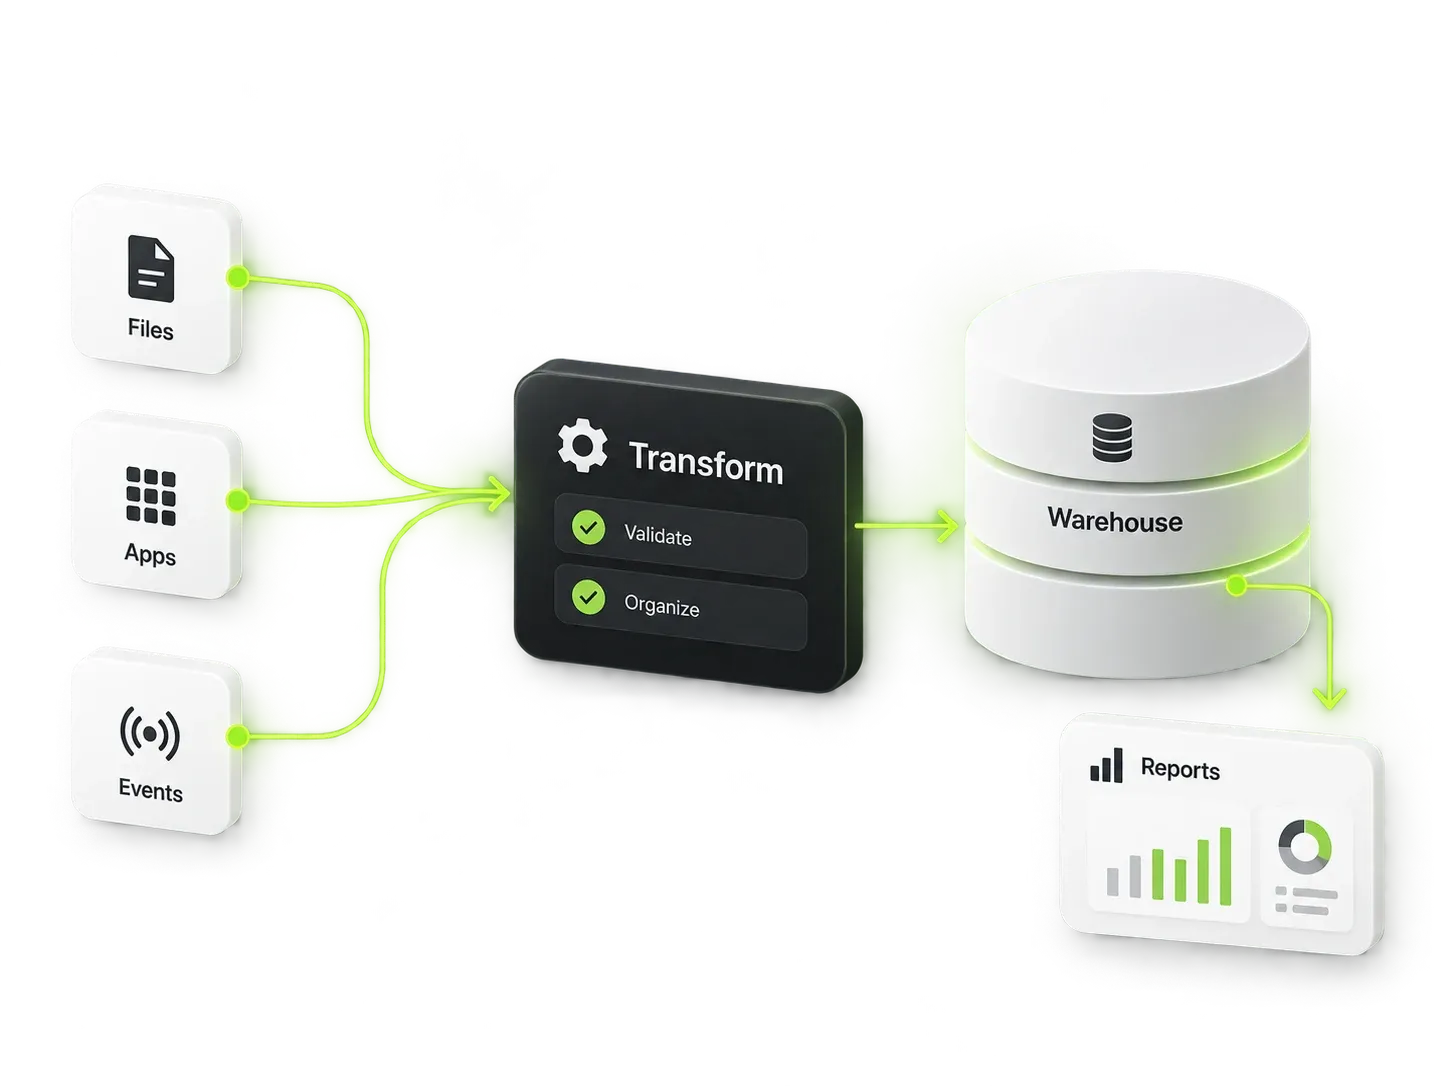
Pipelines that never drop your data.
We build the plumbing that moves your data from wherever it lives to wherever it's needed, automatically, reliably, on time. Clean pipelines today are what make cheap analytics and AI possible tomorrow.
Data engineering connects scattered sources into a dependable foundation for reporting or applications. We document each source, owner, format, update frequency, and access requirement, then agree a destination model and freshness needs. The design considers both current volume and expected growth so infrastructure remains understandable and proportionate.
Pipelines include agreed extraction and transformation steps, validation checks, scheduling, and failure reporting. We document lineage and recovery procedures so your team can trace a number to its source and respond when a feed changes. Historical migration, sensitive-data handling, retention rules, cloud costs, and ongoing operation are explicitly scoped before implementation.
Built around your problems
Every line item below exists because a client once paid the price of not having it.
Everything in one place
Sources consolidated into a single warehouse. Your analysts stop playing 'which export is current?'
Fresh data, automatically
Scheduled ingestion with alerting on failure. No nightly manual exports, no silently stale reports.
Built to be trusted
Validation checks catch broken rows before they pollute reports. You find out from an alert, not a client.
Cheap to run
Right-sized infrastructure with no surprise cloud bills. We've seen what over-engineered pipelines cost: it's not pretty.
Documented lineage
Every metric traceable to its source. When a number looks wrong, you can find out why in minutes.
Ready for AI
Clean, structured, centralized data is the prerequisite for every analytics and AI project you'll want next.
Our stack
Pick a plan
Clear scopes, fixed prices. Every plan can be tailored: the quote you approve is the invoice you pay.
$1,000
One reliable pipeline, end to end.
- 2-3 sources → one warehouse
- Daily scheduled loads
- Validation + failure alerts
- Lineage documentation
$1,700
A small but serious data platform.
- Up to 6 sources
- Transformations + quality tests
- Airflow orchestration, retries
- Runbooks + handover
$3,000
Always-on, at any scale.
- Legacy & complex sources
- Hourly / real-time pipelines
- Cost-optimized infrastructure
- 1 month of tuning included
$1000
3-5 weeks
Final quote depends on scope: you always get a fixed price before we start, so there are no surprises.
Questions clients ask
Who pays for the cloud infrastructure?
You do, directly to the provider; we keep it in your account with cost alerts configured. For most small businesses this runs between $10 and $50 a month.
Can you work with our existing warehouse?
Yes. If it's structurally sound we build on it; if it's a mess we'll show you exactly why and quote a migration honestly. No rebuilding for rebuilding's sake.
What data sources can you connect?
Anything with an API, a database connection, or even recurring file exports: CRMs, billing systems, ad platforms, e-commerce, sensors, spreadsheets.
What about compliance and privacy?
We design for it from the start: access controls, retention rules and PII handling agreed before build. We're happy to work within GDPR or your industry's requirements.
LET’S WORK TOGETHER
Ready to get started?
Tell us about your data engineering project; we reply within a day.